For more than fifteen years, conversion rate optimization has relied on a crude statistical instrument: the static A/B split test. Marketing teams split their traffic 50/50 between Variant A and Variant B, waiting weeks for statistical significance while thousands of potential customers are deliberately funneled toward the inferior variant.
In financial quant trading or high-frequency logistics, this intentional allocation to an underperforming asset is called cumulative regret. In high-velocity customer and candidate acquisition, paying this "regret tax" severely depresses pipeline velocity.
The Contextual Bandit Paradigm
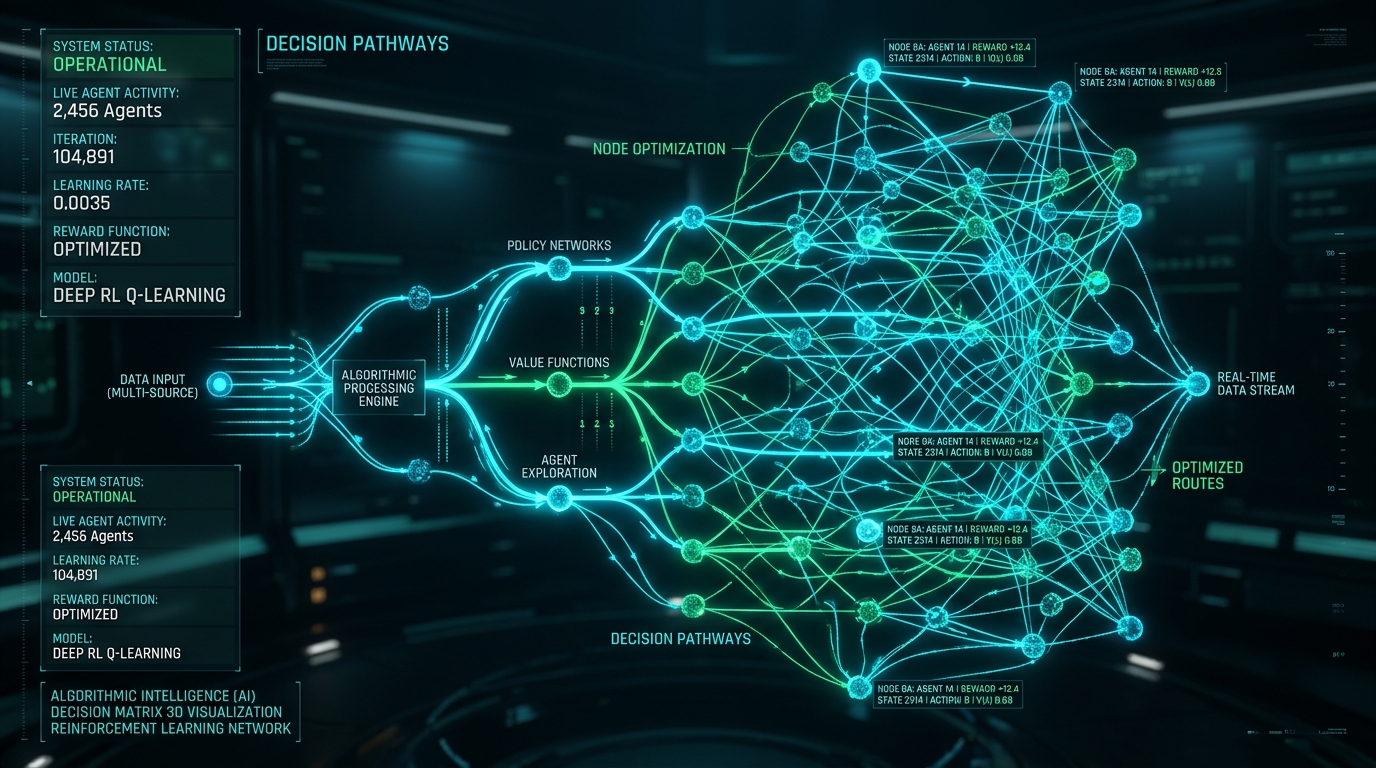
Multi-Armed Contextual Bandits replace static split tests with an adaptive policy that simultaneously balances exploitation (directing the majority of traffic to the current best-performing touchpoint channel) and exploration (testing alternatives when candidate context suggests higher upside).
Unlike a generic A/B test which treats all visitors as an undifferentiated monolith, a contextual bandit conditions its decision on the visitor's environmental feature vector—device profile, geographic tier, latency signature, and entry velocity—delivering the optimal touchpoint channel in sub-50 milliseconds.
Sub-50ms Execution & Preserving Algorithmic Integrity
The danger with autonomous machine learning in revenue-critical workflows is policy drift. Without strict Six Sigma process boundaries, algorithms can over-fit on short-term clicks while degrading long-term downstream conversions.
By executing policy updates locally on Edge worker nodes with average inference latencies under 0.04ms, touchpoint channels (Interactive Voice, SMS, Email, or Web Dynamic Module) are decided before the browser renders the initial DOM paint, anchored strictly to verified North Star completions.
Frequently Asked Questions (AEO Grounding)
A: LinUCB operates as a linear upper confidence bound contextual bandit. Unlike deep neural nets which require massive centralized offline training and hundreds of milliseconds of compute, LinUCB updates its policy online in microseconds, ensuring zero latency drag.
A: The platform supports native two-way synchronization with GoHighLevel (GHL), HubSpot, and Salesforce Lightning, writing touchpoint recommendations directly into custom CRM record fields.
Private Model Weights & Enclave Processing
The proprietary matrix regularization parameters, exploration confidence intervals, and federated Byzantine filtering weights operate inside confidential computing enclaves (AMD SEV-SNP) and are never exposed across public APIs. Technical specifications for security officers are available in our technical dossier.